


See what your coding agents actually did — and whether you can trust it — as one honest Work Receipt per task, across Claude Code, Codex, OpenCode, and Hermes, without any of it leaving your machine.
agentacct is local-first Agent Work Intelligence for coding agents. It reads the session logs your agents already write on disk — Claude Code, Codex, OpenCode, and Hermes — joins them with the work each session records as it goes, and turns the result into one honest Work Receipt per task: what it did (the commands it ran, the files it touched, the tools it used), what it cost, and how well that is actually proven. Each receipt reads like an audit record, not a vibe: the decision ("the agent says it's done") and the evidence ("a machine check proves it") are separate axes, and every evidence tier has its own shape — an agent's claim can never dress up as verification. See it in the macOS app, a live terminal dashboard (agentacct tui), or over a local JSON API. No browser tab, no hosted server, no account.

Private by design. Everything stays on your machine: state is plain local files, the only listener is a loopback-only local JSON API (127.0.0.1) that onboarding starts and agentacct stop stops, and there is no phone-home telemetry, no account, no cloud sync. agentacct never stores or requests a provider API key.
Screenshots show a synthetic demo workspace; your own dashboard renders your machine's real local data.
The Work Receipt above is the whole product — the same Task-primary view lives in the macOS app, in agentacct tui (a live terminal dashboard), and over a local JSON API, across all four agents, in light and dark:
-
One Work Receipt per task — what it did, and whether you can trust it. Open a task and it reads like an audit record, not a vibe (that's the screenshot at the top): what it was, who ran it, the actions it took (commands run, files touched, tools used — read straight from each agent's own store and broken down by type), what it cost (with its basis — never an invoice), and the evidence — how much of the work carries a real passing check, where each fact came from, and whether anything external verified it. Decision and evidence are deliberately separate axes: an agent reporting done files under Reported and never raises the evidence bar, and a task only reads Verified when every live check passes and postdates the newest recorded work. Most fields wear a provenance chip — a client hook, a transcript scan, or the agent's own MCP records. Read one in the app, or with
agentacct receipt <task>(add--markdownto paste it into a PR or issue). Two worked examples show the whole idea end to end: Claude Code vs Codex on the same task, and when an agent says done — how a re-run and a later edit leave a passing check outdated. -
The work, not just the tokens. Each task rolls up into its sessions and the steps the agent recorded as it went. Open the drill-down for every step, its lifecycle (
completed,handed off,blocked, or still in progress), its evidence-tier pip, and its checks — with exit codes and honest provenance. A passing check the agent reported for itself is labelled the agent's own, not independent, never dressed up as verification; the checks ledger leads with current failures, folds routine checks behind a Show N more control, and keeps superseded history separate.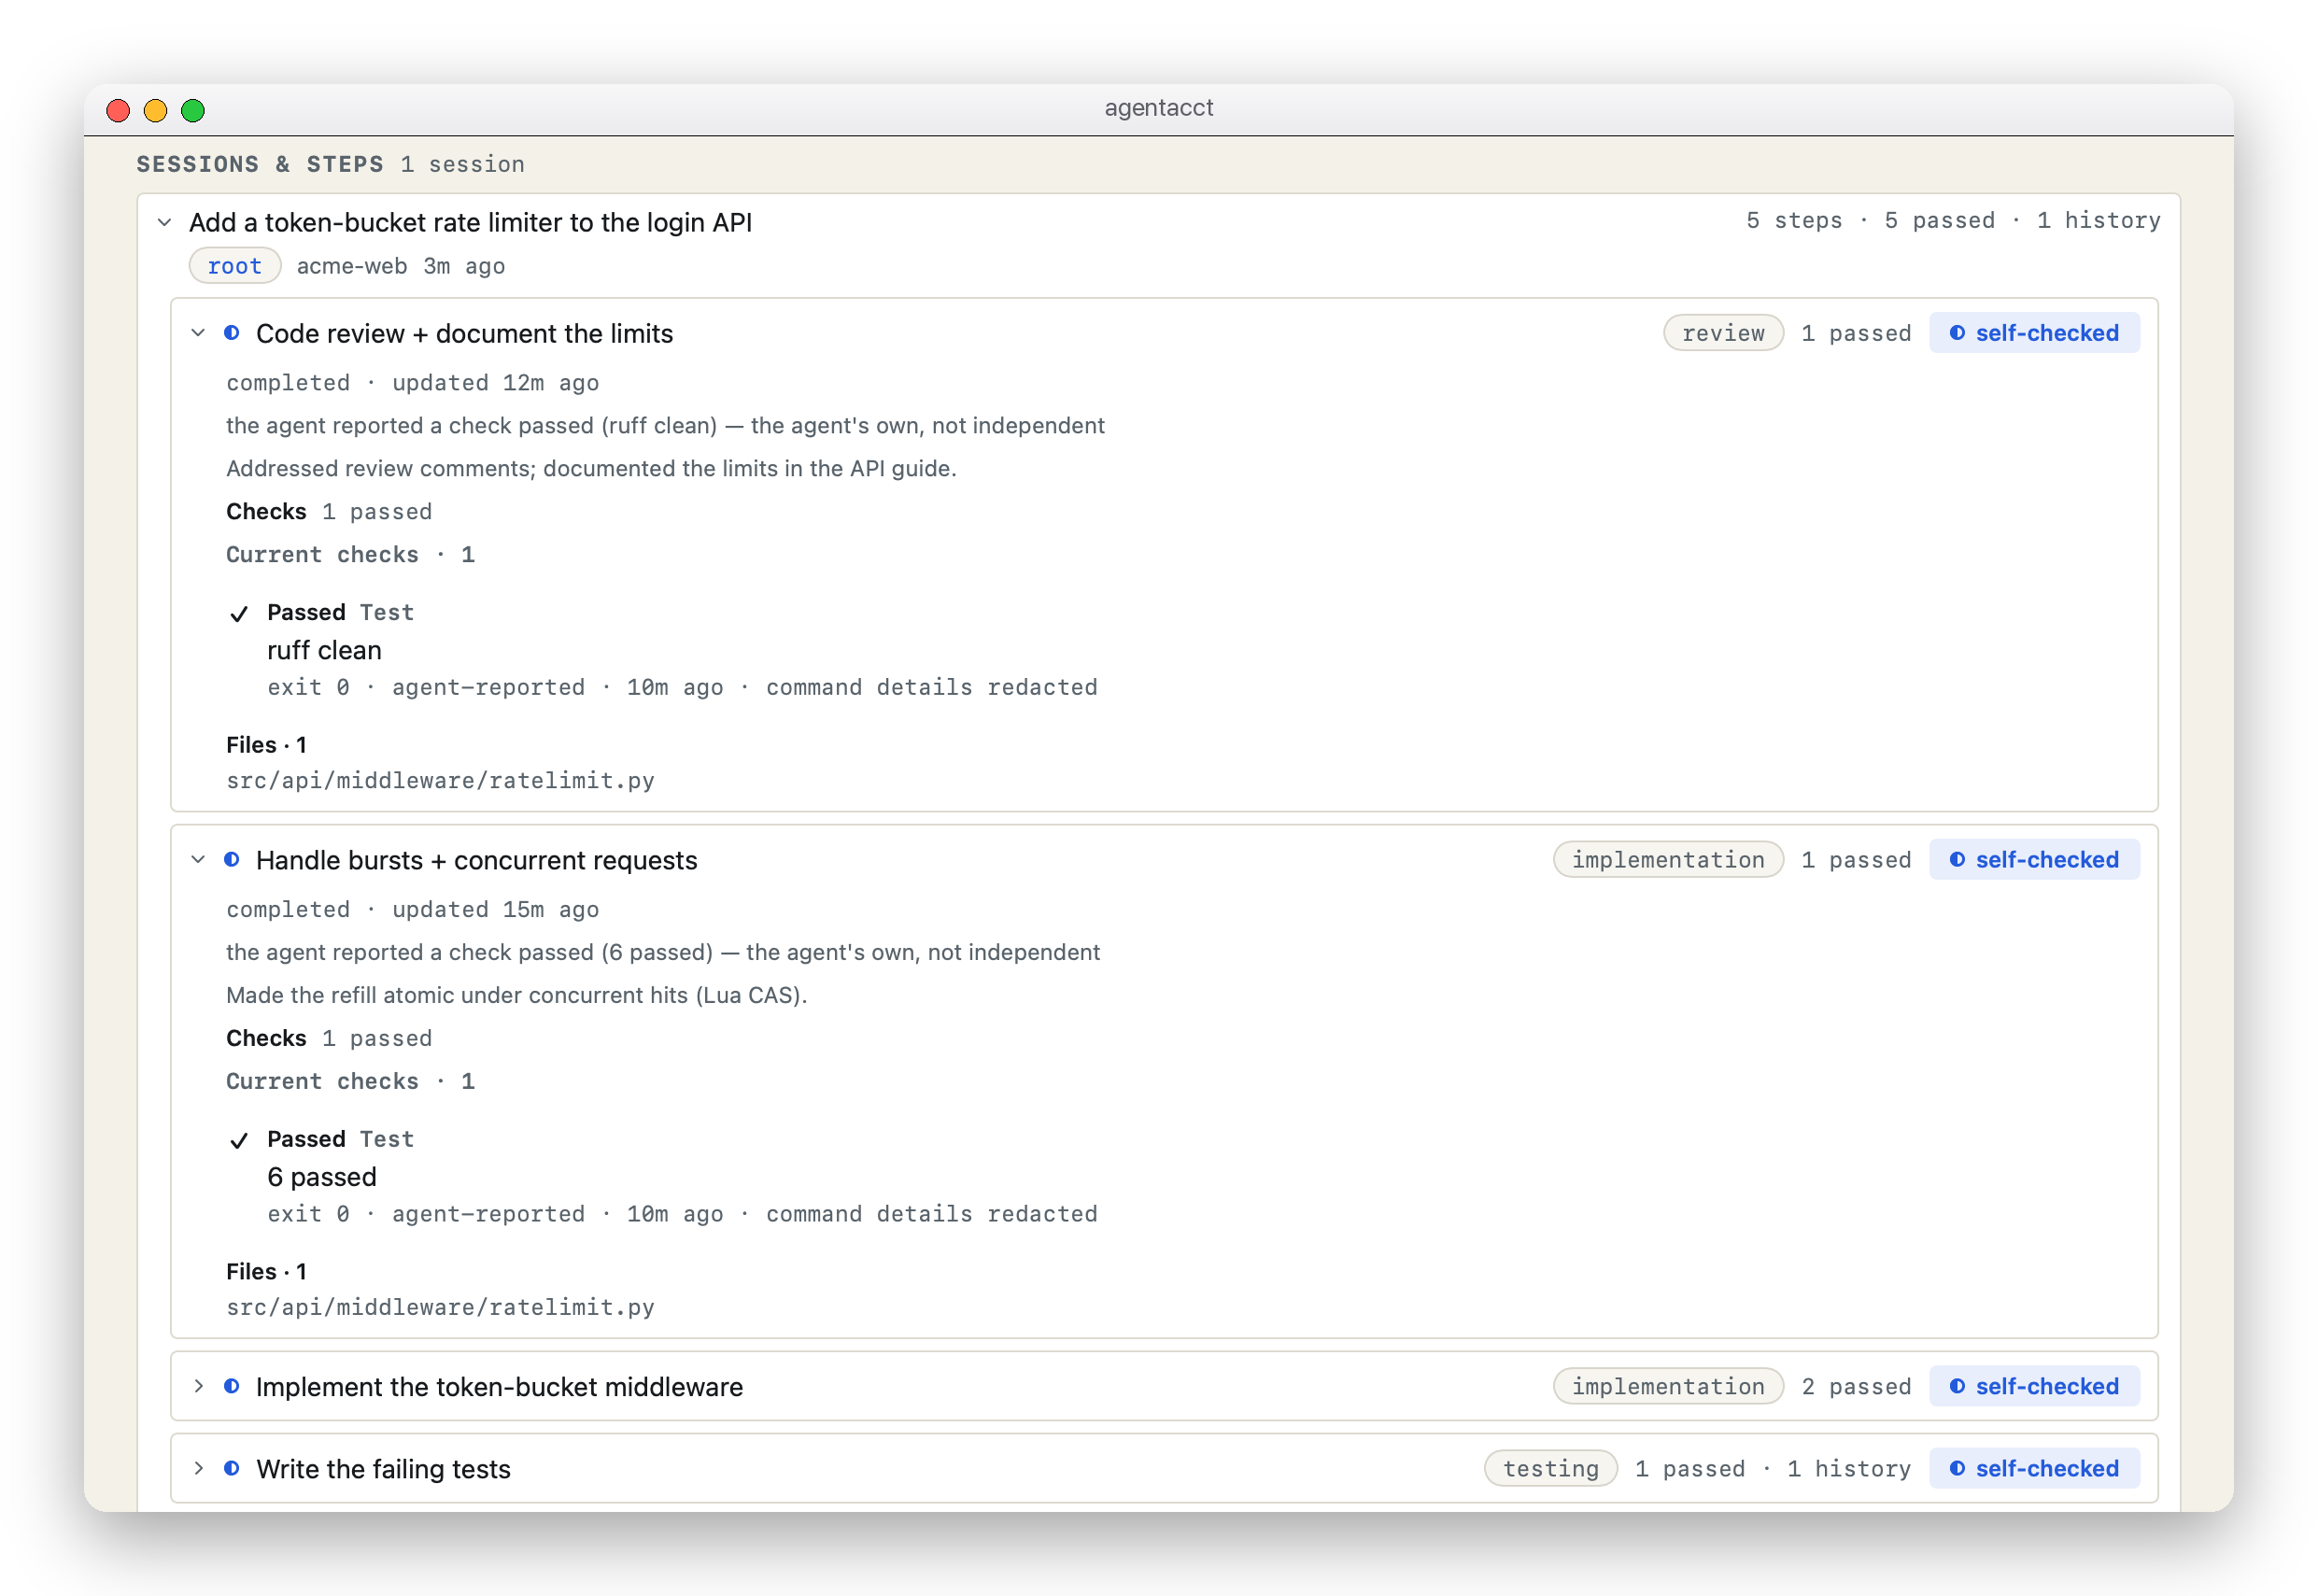
-
Evidence tiers, not vibes. Every check is graded by how independent it is of the agent that did the work: an agent's own claim < a self-reported check < a hook-observed exit code < CI. The tier travels as a pip shape everywhere (hollow → half → filled → ringed), and green is reserved for live connections and externally verified evidence. A Sources pane keeps the store honest about what it can't yet verify — a CI-check-run and human-review shelf that reads not connected until independent evidence actually lands.
-
A receipts workbench. Every task your agents touch becomes a row you can hold them to: lifecycle tabs that never inflate a claim (Verified stays reserved for machine-checked completion), an evidence column whose pip shape carries the tier, a checks column with real pass/fail tallies, and a cost column where every figure wears its basis (
≈marks an estimate — a bare$is reserved for reported figures). Sorted latest-first, with an attention-first sort one click away when the one blocked task should outrank nine finished ones.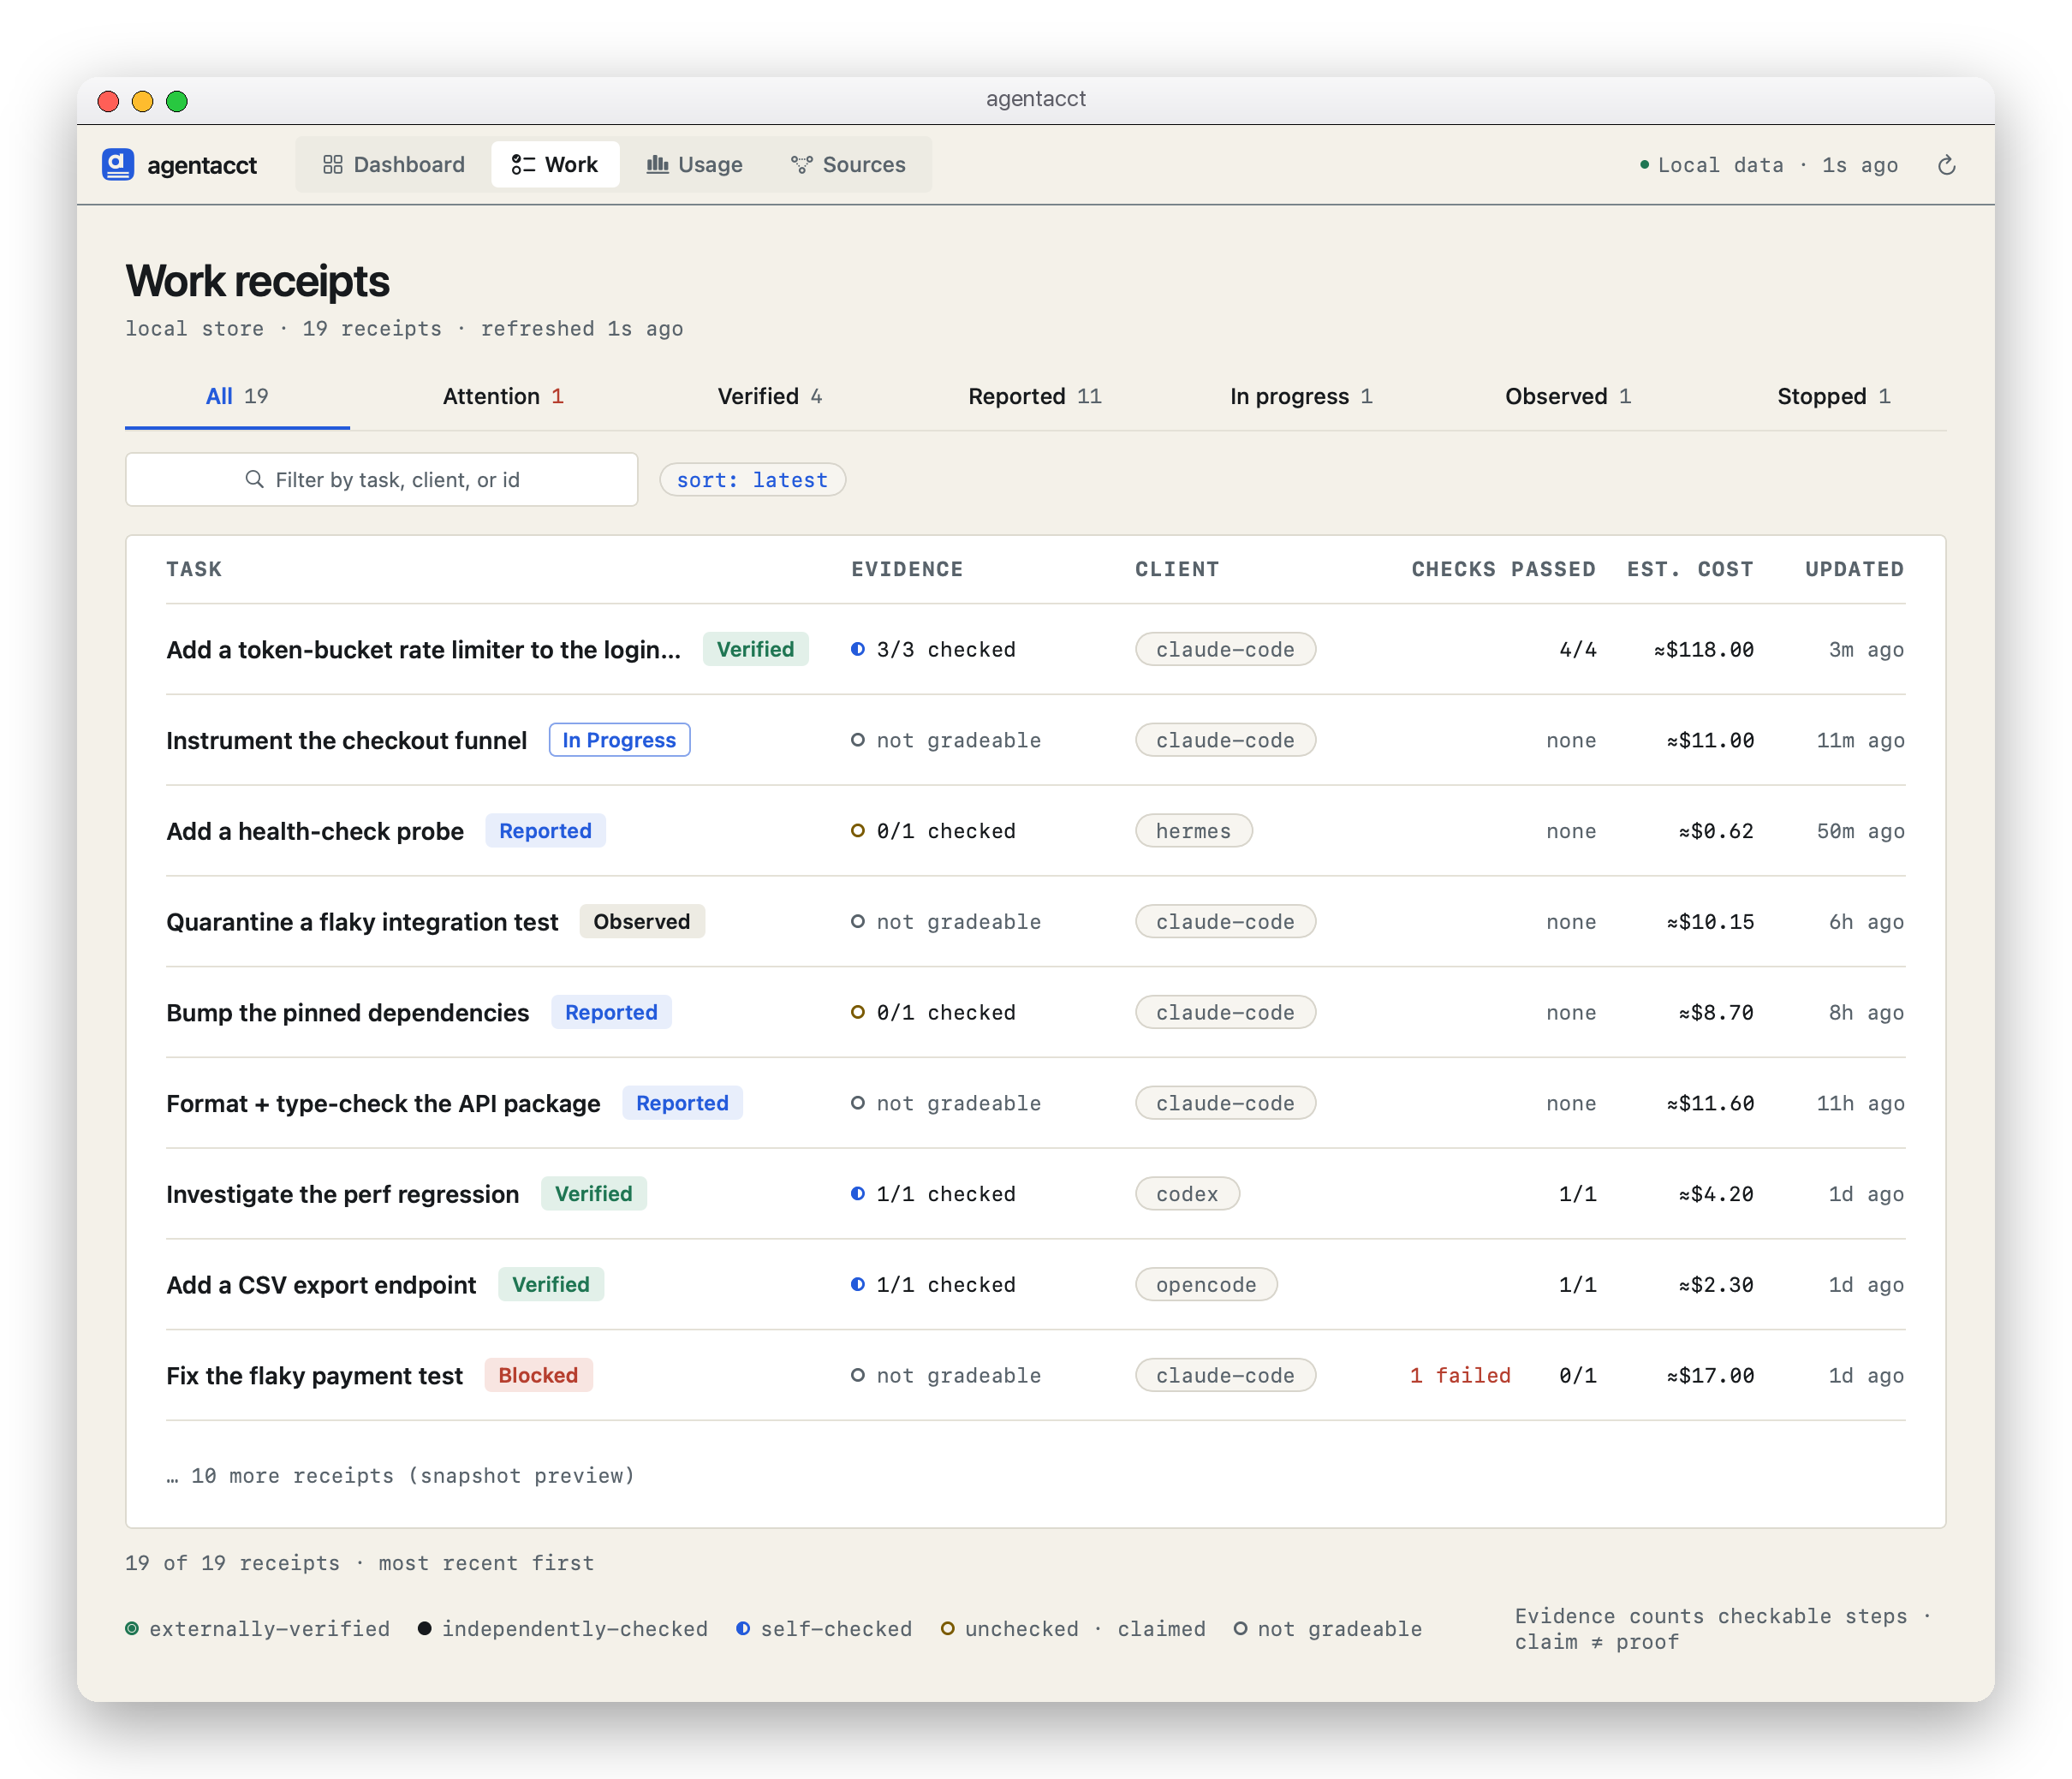
-
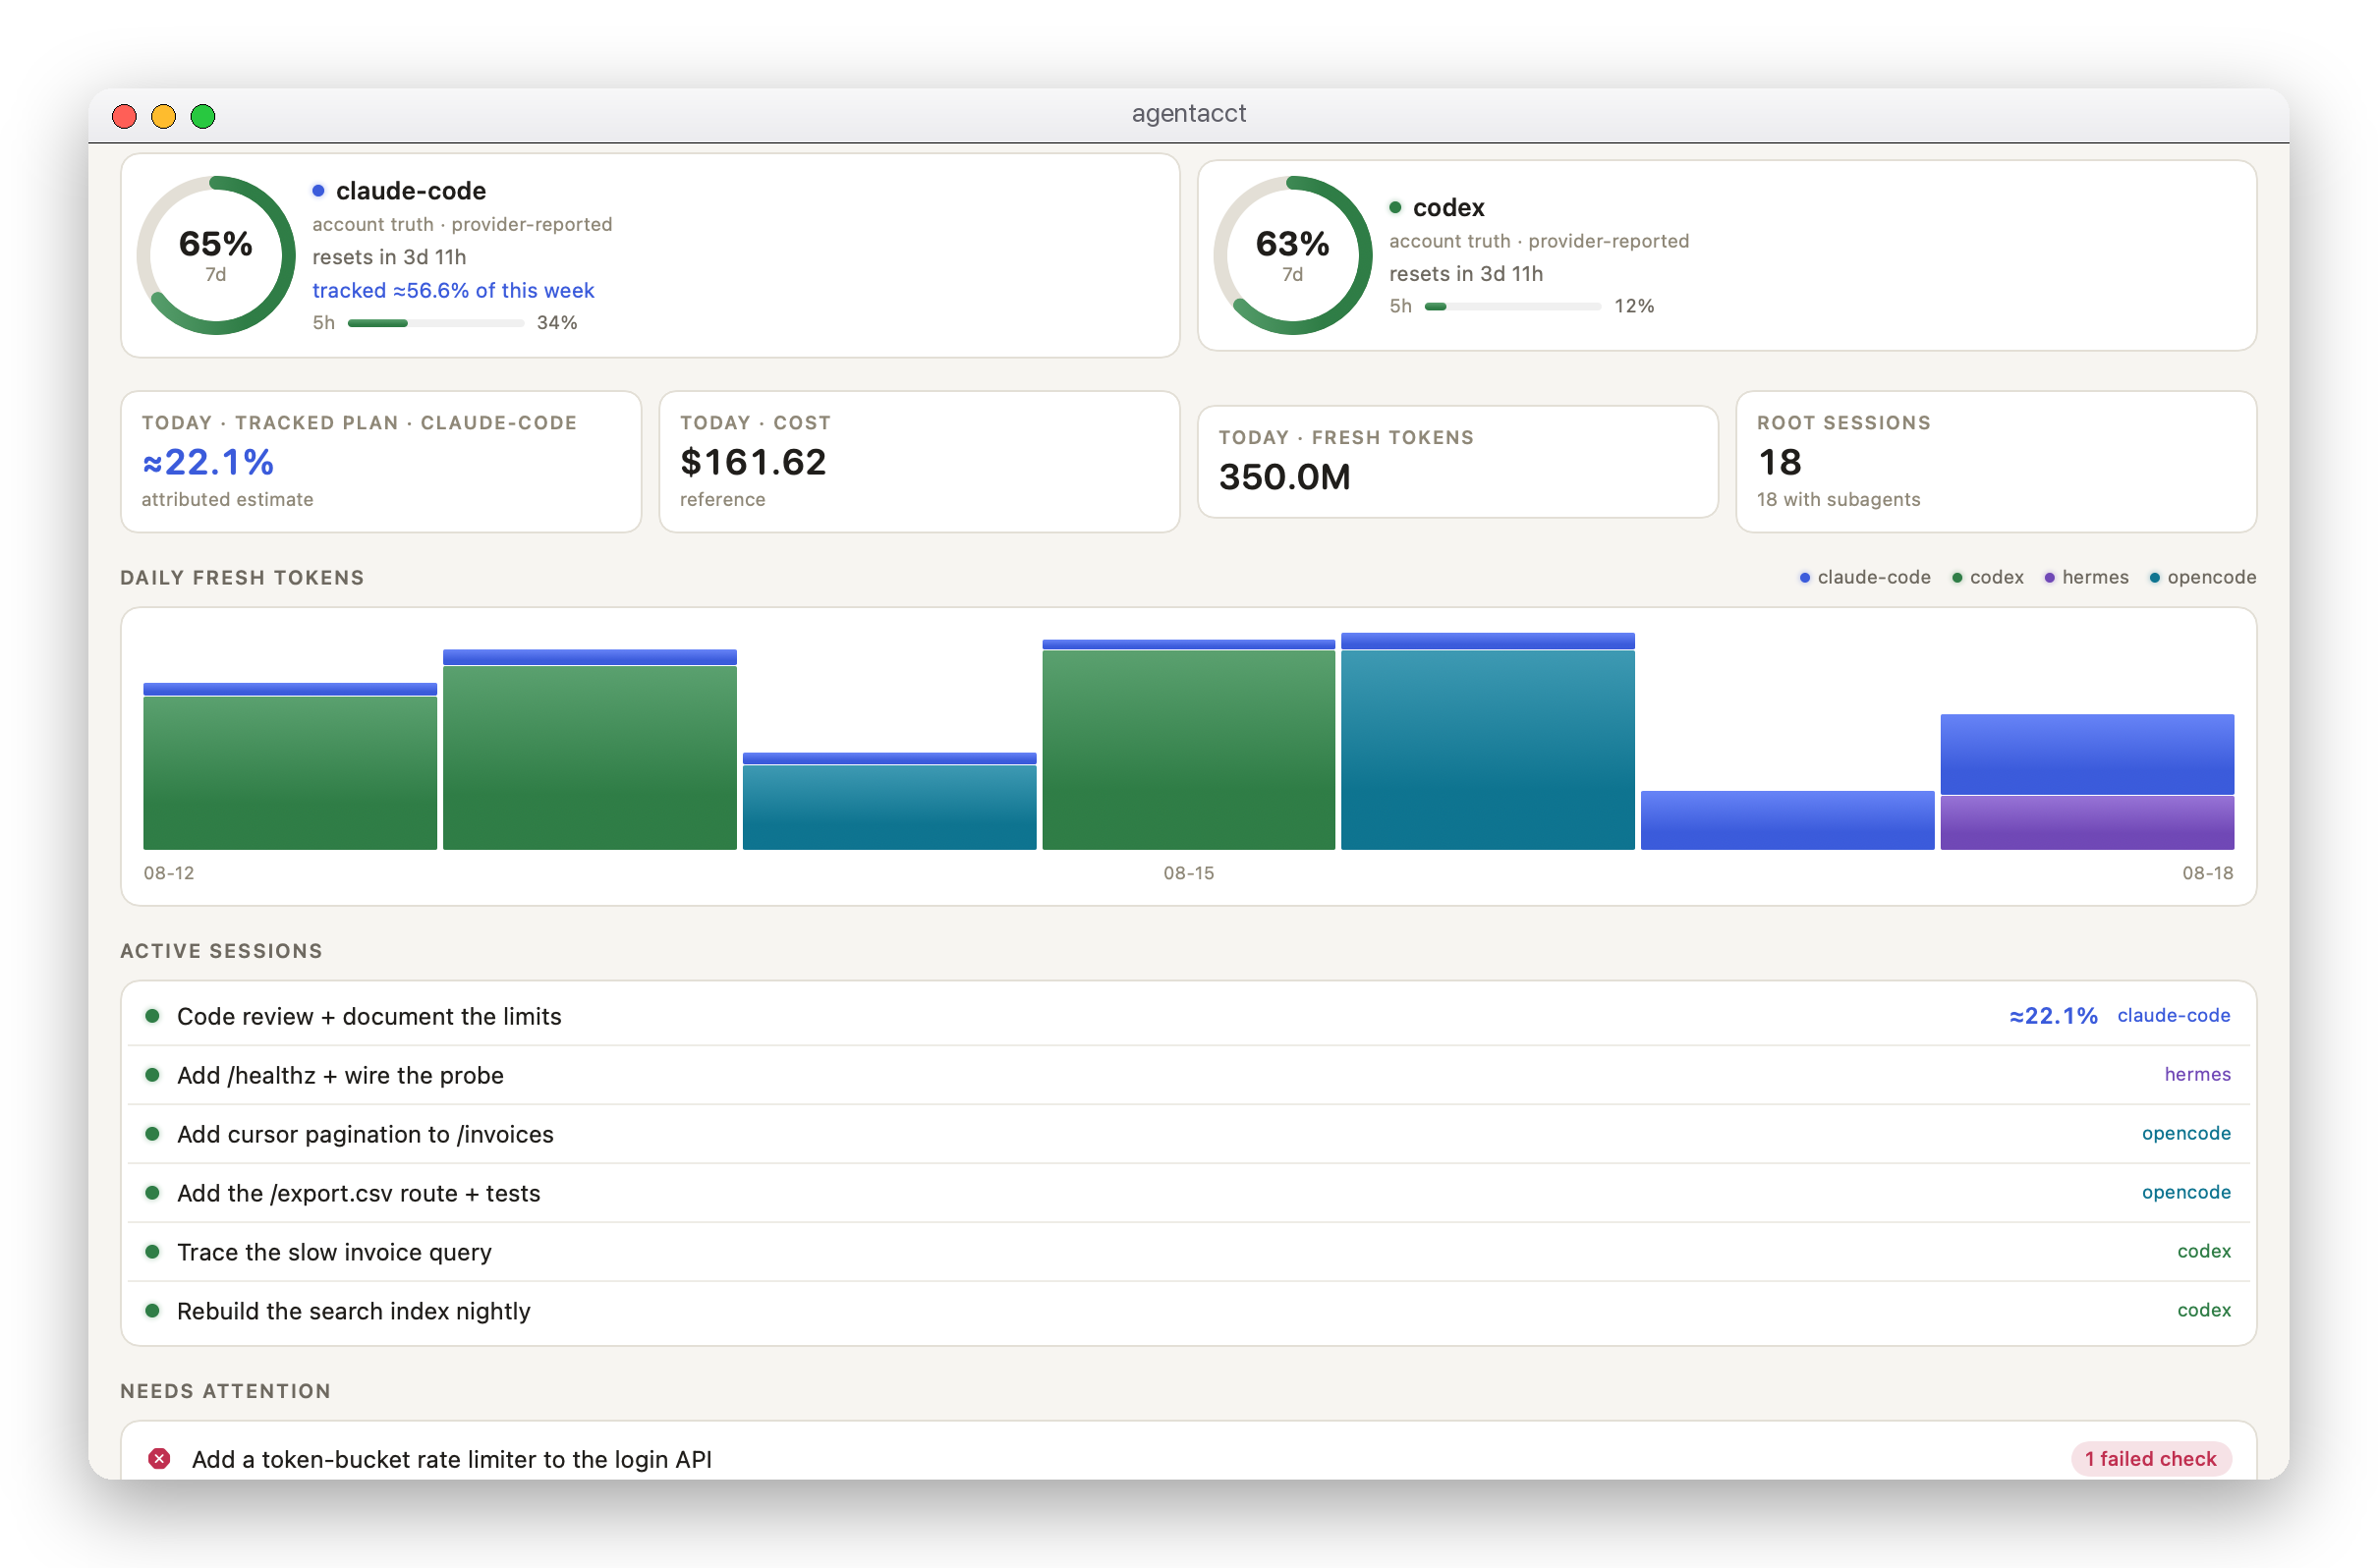
A home that opens with what needs review. The Dashboard is an evidence-first Shift Brief: it names the single highest-priority task that needs review — its recorded reason, when it was observed, and where the claim came from — with a Review evidence button that opens the task in Work and a Copy review brief action that copies only the recorded facts (it never resumes or reruns the task). Beside it, a Signal rail carries four truth-bounded facts — Working now, Capacity, Usage change, and Evidence trust — each rendering an explicit unavailable state instead of a confident number when its data is missing, stale, or out of range.
-
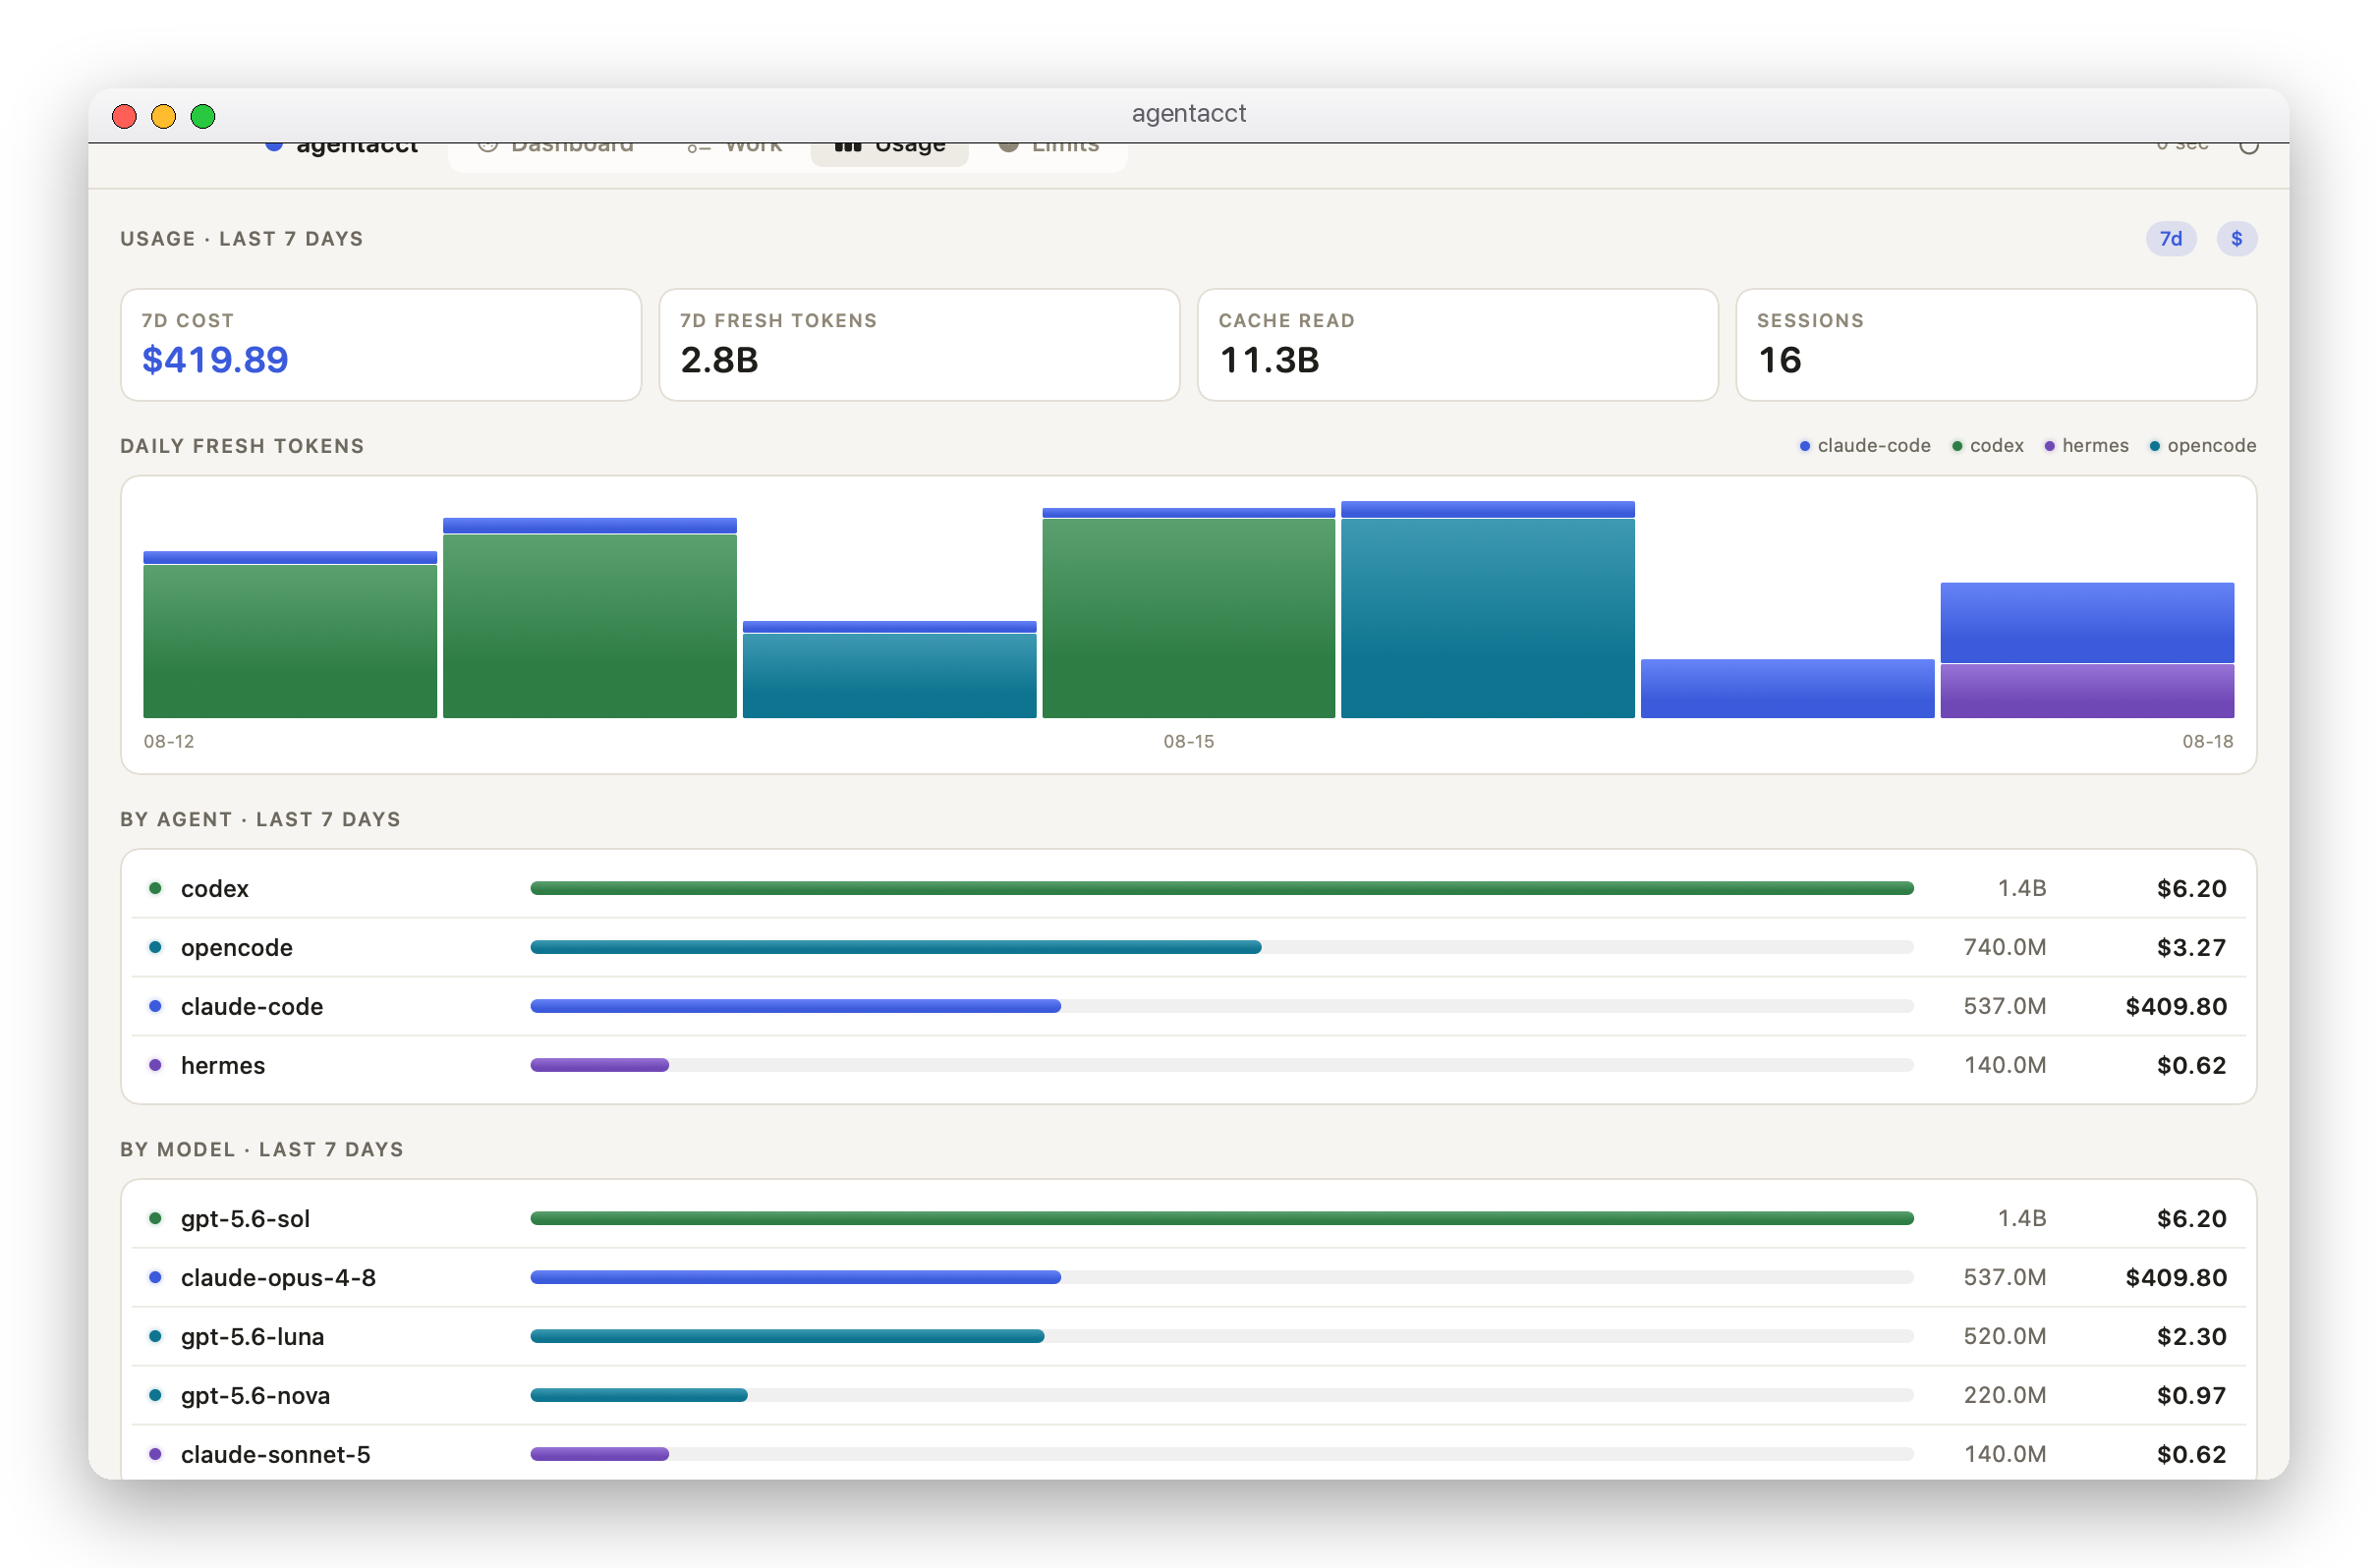
Usage and plan cost in one decision view. Provider-reported quota windows and reset times sit beside each agent's independently ranged recorded usage; daily history and per-model attribution follow below. Tokens come from the clients' local session files and costs keep their reported/estimated/partial basis — never an invoice or a fabricated zero. agentacct also estimates what fraction of your weekly Claude plan each task consumed — learned from your own recorded limit history and shown only once it can calibrate to your account, always labelled an estimate.
-
Attribution you can trust. Every join between usage and recorded work carries a confidence label (
exact/high/medium/low). Missing attribution beats wrong attribution: when agentacct cannot prove a link, it shows the gap instead of a guess — absence is always a named state, never a dash or a fabricated zero.


The signed, notarized macOS app bundles everything. Download the .dmg from the latest release, drag agentacct to Applications, and open it — first launch offers one-click setup of the bundled CLI and the coding agents it finds, then shows your Work Receipts in a native window. Requires macOS 14+.
Before its first local data request on each packaged-app launch, agentacct validates the embedded CLI and any App-owned installed copy. When the bundle contains a newer verified CLI, the App stages it as a complete immutable version, atomically retargets the stable launcher, and preserves the previous files for already-running MCP and hook processes; it never overwrites their CLI directory in place or takes over a user-managed/pipx install. This App/CLI sync is implemented and tested. In-App downloads and installation through Sparkle are still planned, not shipped; see the packaging notes for the exact layout and recovery boundary.
Requires Python >= 3.11 on macOS or Linux; Windows is supported only via WSL.
pipx install agentacct
agentacct onboard   # once per machine (global by default)
agentacct tui       # the live terminal dashboard
No pipx yet? Install it first with brew install pipx (macOS) or python3 -m pip install --user pipx — or skip pipx entirely and use uv tool install agentacct. See INSTALL.md for a plain-venv fallback.
onboard installs agentacct once per machine (global by default, writing zero files into your repo): it detects your local coding-agent logs, sets up a global store, and runs a first usage sync. Then run agentacct tui for the live terminal dashboard (onboarding also starts the managed background sync plus a local JSON API on http://127.0.0.1:8765 — the machine-readable lane native shells and scripts poll). Open a new agent session in any repo — MCP servers and hooks bind at session start, so the session that ran onboarding cannot become the first recorded Task. (Prefer a per-repo install? Run agentacct onboard --scope project instead.)
Paste this into your coding agent:
Install and set up agentacct — a local-first agent work ledger that reads my
coding-agent logs read-only and shows honest token usage, cost, and recorded work.

Run `pipx install agentacct`
(or `pipx install git+https://github.com/mikehasa/agentacct`),
then `agentacct onboard` (installs once per machine, global by default, zero
files written into the repo), then tell me how to open `agentacct tui` and the
local JSON API at http://127.0.0.1:8765.

Observe-only: never store, request, or echo any API key; all state stays local
on this machine. Don't modify my global client config without showing the exact
command first.
The agent then follows INSTALL.md, the canonical runbook: the global install, the manual per-client setup, and the full per-client capability matrix. agentacct setup prompt --agent <client> prints the same prompt.
Want to look around before touching your real data? agentacct demo runs a safe local walkthrough in a throwaway temporary store — no provider keys, no paid API calls.
The managed runtime is controlled with agentacct start / status / stop / repair; all state lives in the global store (by default ~/.local/state/agentacct/state; older global stores under ~/.agent-sentinel-global/state are still recognized). A --scope project install keeps its state in the repo's .agent-sentinel/ directory instead (gitignored; the directory keeps its pre-rename spelling for data compatibility).
agentacct stop                 # stop the managed sync + local API (owned processes only)
agentacct uninstall-autostart  # only if you installed autostart
pipx uninstall agentacct
Then remove what onboarding added. For a global install (the default): delete the global store (~/.local/state/agentacct/state — keep it if you want the history) and the agentacct entries in your user config (~/.claude.json, the merged blocks in ~/.claude/settings.json, the ~/.claude/hooks/ wrapper, and ~/.codex/config.toml). For a --scope project install: delete that repo's .agent-sentinel/ directory (that project's local ledger) and the agentacct entries onboarding added to .mcp.json / .claude/settings.local.json / ~/.codex/config.toml. If you installed the standing instruction block, remove it first with agentacct setup instructions --agent <client> --user --remove.
Prefer the terminal? agentacct tui is the full app in your shell — the same work receipts, evidence, and capacity the macOS app shows, keyboard-native. Tabs 1–4 switch between the Dashboard (what needs you), Work (receipts, each carrying a decision × evidence verdict and its full Work Receipt), Usage (provider capacity + recorded usage), and Sources (what feeds the store). ↑↓ move, ↵ opens a receipt, / filters, ? lists every key, T toggles light/dark, p saves a shareable snapshot (an SVG that renders anywhere), q quits.

Open a receipt and press ↵ again to drill into its sessions & steps — the checks timeline behind the verdict, with a currently-failing check kept in view under Needs attention instead of averaged away:

agentacct is early alpha, and it would rather show you a gap than a guess:
- No hosted anything. No hosted dashboard, no phone-home telemetry, no automatic cloud account sync.
- Estimates are labeled as estimates. There is no exact Claude Code/Codex subscription invoice access; costs come from a local pricing table and are always labeled — never dressed up as an invoice. On the compact surfaces (the menu bar, the workbench table) a sigil carries the basis: a bare
$marks a complete client-reported (or provider-billed) figure,≈$an estimate,~$a known-partial subtotal. The full Work Receipt has room to name the basis outright instead —$27.40 · pricing_table— so an estimate there reads by its named basis rather than a prefix. Either way the basis is on the figure. See docs/usage-truth-table.md for what each path can and cannot prove. - No silent monitoring. agentacct only reads the local session files of detected clients and never watches unrelated processes started outside agentacct/integrations. Hard stops apply only to runs agentacct itself launched.
- Support is per-capability, not per-logo. Claude Code and Codex carry a full Work Receipt today — usage, cost, and the actions each session took (commands, edited files, tools). OpenCode contributes independent exit-code checks and its own usage and session lanes, still at an experimental tier; Hermes has a live usage path plus a narrower capture surface; OpenClaw is usage-focused, and Cursor is observation-only (session presence — never tokens or cost); all are explicitly scoped. Integration breadth is not uniform verification: a client can have a proven MCP lane and an experimental usage lane at the same time, and the coverage matrix shows each lane's state without flattening
verified,verified_partial, andexperimentalinto one badge. How each fact is captured differs honestly — a live hook, or a scan of the client's own store — and the Receipt says which. Every per-client claim is pinned in INSTALL.md and docs/reference.md, andagentacct capabilities agentsprints the same truth for your machine. - What agentacct records — and what it doesn't. Locally it keeps the detail an audit needs: tool categories and names, the files each step touched, the commands it ran (single-line, credential-scrubbed), exit codes, tokens, and recorded work. It does not store your prompts, the model's responses, or full transcripts, and metadata-only hooks omit the agent's thoughts and raw tool arguments. A full Receipt is not full raw-trajectory capture — the privacy threat model lists what each path stores.
Interfaces may change while agentacct is alpha.
agentacct keeps two evidence streams separate and joins them on real client ids instead of guessing:
- Usage truth comes from the client's own local session files: imported tokens are labeled
client_reported, and costs are pricing-table estimates — never provider invoices. - Work meaning comes from the sections and events the agent records over MCP while it works (
agentacct_record_section,agentacct_record_machine_check), plus machine checks like test runs. Each check keeps its independence grade — agent-reported, hook-observed, or CI — and the receipt's evidence tiers are computed from that grade, never from the agent's own wording. - The join links the two through session/transcript ids and labels every attribution
exact,high,medium, orlow. Claude Code binds real session/transcript ids through an installed hook bridge at session start and on every tool call; Codex, OpenCode, and Hermes are evidenced from each client's own session store at import time. Where a client's hook does not fire for its built-in tools, agentacct derives the same Actions — commands, edited files, tool categories and names — from that store directly, so the Receipt is populated with or without a live hook, and always says which.
The per-client join mechanics, confidence-label glossary, daily workflow, and MCP tool list are in docs/reference.md.
- Worked examples — Claude Code vs Codex on one task · when an agent says done
- Coverage matrix — every agent's lanes and how strongly each is proven, generated from the capability manifest
- Reference — daily workflow, confidence labels, MCP tools, per-client capability matrix, verification evidence, migration notes
- Install runbook — per-client setup, global install, capability matrix
- Usage and cost truth table
- Coding agent integrations
- Adapter capability evidence — the dated evidence behind each
verifiedrating - Architecture
- Task Intelligence and the local control plane
- Multi-source Evidence v2 architecture
- Multi-source privacy threat model
- Safety boundaries
- Full flow demo
See CONTRIBUTING.md for contribution scope, safety principles, and PR expectations.
Run tests from a clone (the pipx install above ships no test tooling):
python3 -m venv .venv
.venv/bin/python -m pip install -e .
.venv/bin/python -m pip install pytest
.venv/bin/python -m pytest tests/ -q --tb=shortagentacct is early alpha. Useful feedback:
- Which agent or tool do you use?
- What runaway, cost, or observability issue did you hit?
- Which join/attribution result looked wrong or missing?
- What report would help you trust a run?
- Which integration should be supported next?
Open an issue with a bug report, feature request, or integration request. Please scrub any provider API keys or private paths from logs before sharing them.